Skip to content

213 posts tagged with “process”

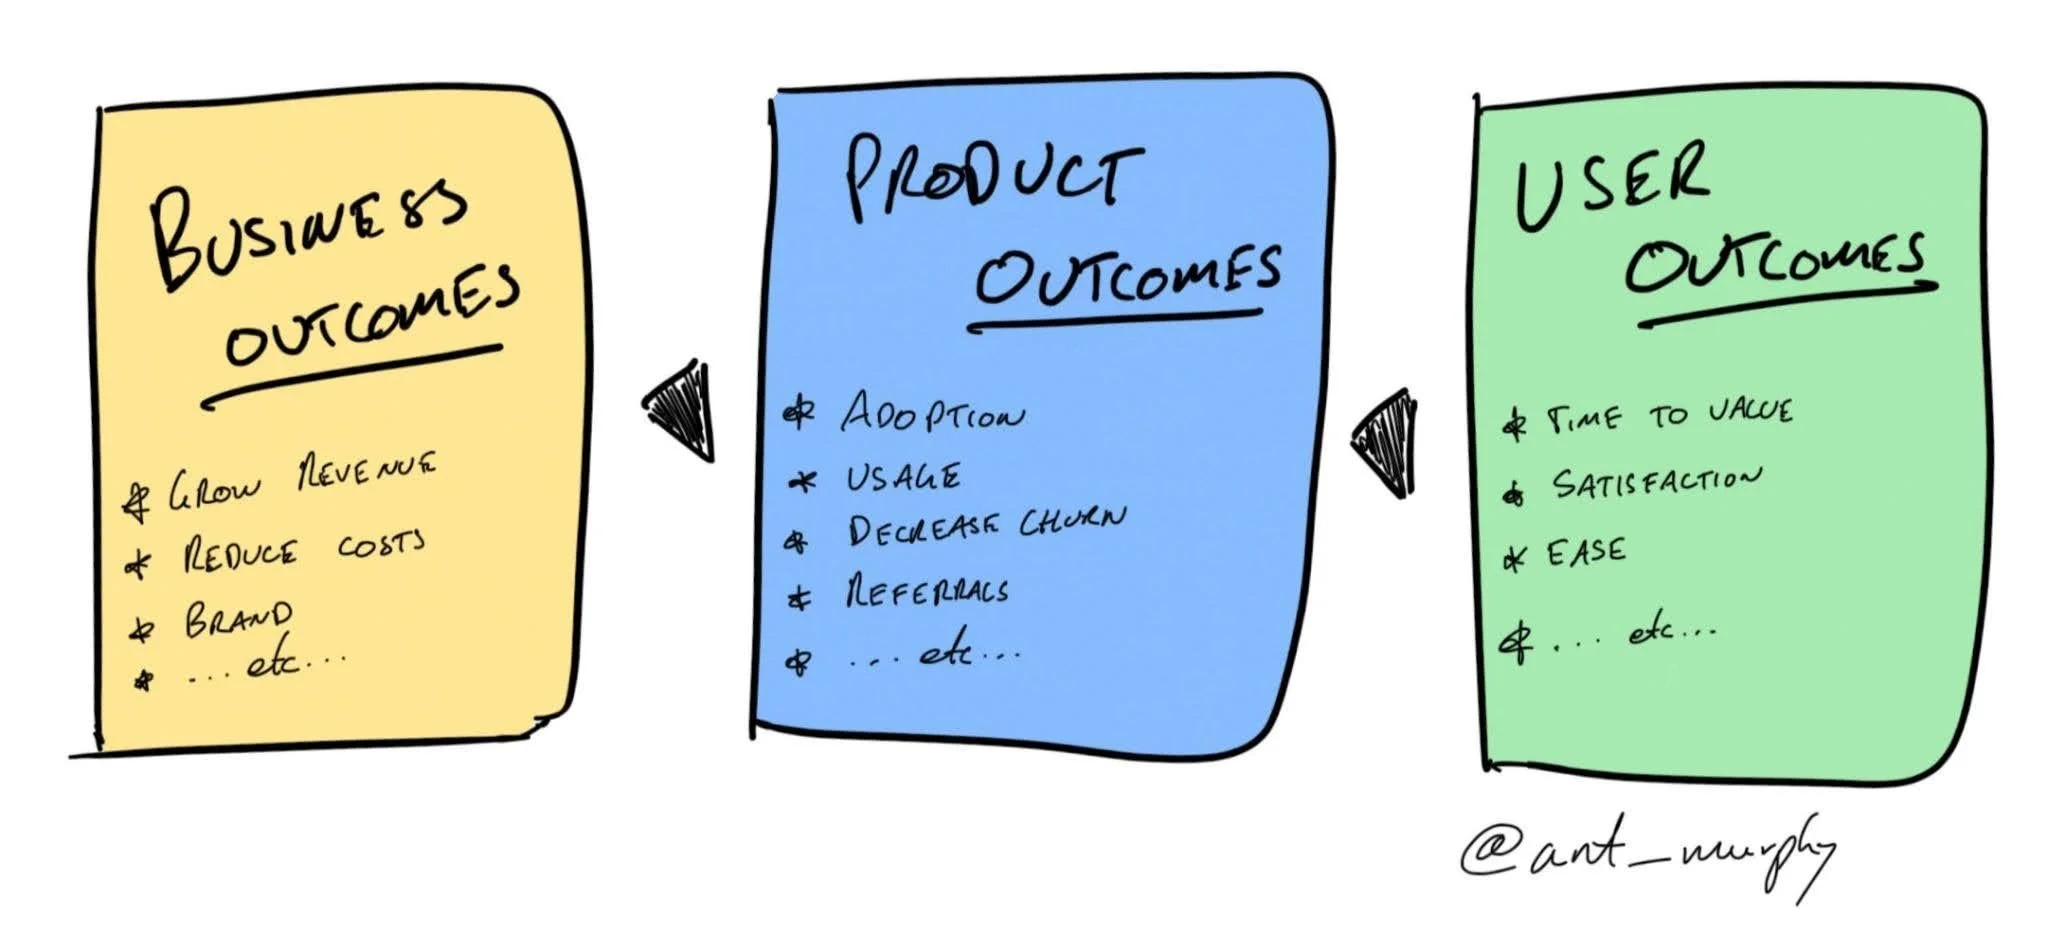
Pick one metric on your team’s dashboard. What decision would change if it moved?

Ant Murphy offers two questions for finding out:

Two of my favourite questions to ask about any product metric are:

  1. What are you trying to learn?

  2. What change will you make as a result?

There are thousands of things you can measure, but measuring for measurement’s sake isn’t helpful. It needs to drive decisions.

The second question puts a team on the hook before the data arrives. It forces the decision rule into the open, when there’s less temptation to rationalize whatever the chart happens to show.

Murphy also argues that difficulty assembling a metric can be evidence that the team has stopped settling for whatever its analytics tool already exposes:

And that’s the trap that Ridgway was describing all those years ago and it’s still relevant today.

So I see friction as a good sign - it means the metric is:

  • Unique: specific to your product and your problem, not pulled off the analytics shelf
  • Meaningful: tied to the behaviour change you actually care about
  • And thought through: you’ve actually unpacked what you’re trying to learn

So it’s worth pushing through the friction. I’ll take a meaningful proxy, or a smaller sample of something high-quality, over a generic metric every time.

Product analytics dashboard showing metrics connected to decisions.

Measuring ≠ Learning

A dashboard becomes useful only when each metric answers a specific question and changes a decision. Otherwise it is measurement without learning.

antmurphy.me icon antmurphy.me

Kai Wong asked 32 design leaders what they do when companies mistake faster production for faster design. He begins with a plumber:

Imagine a plumber walks into your house, looks at the pipes for a few minutes, tightens one valve, and hands you a bill for $300. Your first reaction might be, “Anybody could have turned that valve.”

Wong borrows a distinction from neuroscientist and Tiny Experiments author Anne-Laure Le Cunff: “the ancient Greeks had two words for time, not one.”

The first is chronos: time as quantity. The number of hours in a day, the number of weeks in a year. This is the time your projects are based on.

The second is kairos: time as quality. Not how much, but how good. Le Cunff frames it not just as better quality time: it’s having the time to recognize a pattern from everything you’ve seen before and know it’s the right time to act.

[…]

Design runs on Kairos. AI might have made things faster, but businesses don’t need 500 screens by lunchtime.

They need the right solution to their problem. And that comes from the quality of thinking that happens along the way.

Wong closes:

When AI is your competition, the temptation is to compete on its terms. Faster. Cheaper. More. You’ll lose that race. And you’ll produce worse work while you lose it.

Compete on the thing AI doesn’t have. Judgment.

Generation is chronos, and chronos is cheap now. Judgment is kairos, and kairos is the whole job. Protect it. Make it visible. When someone asks you to cut the timeline in half, be ready to explain clearly what they’d actually be cutting.

Design leader reviewing work at a desk amid rapid interface production.

What 32 design leaders do when told to move faster

AI makes production cheaper, but it does not make judgment cheaper. The time to recognize the right solution is still the work design leaders need to defend.

uxdesign.cc icon uxdesign.cc

Lola Famulegun, writing for Nielsen Norman Group, separates the UX metrics that describe design performance from the business metrics executives use to judge an investment:

Upstream metrics tell you how the design performed. Examples include task success rates, error rates, SUS scores.

Downstream metrics capture what changed in the business as a result. Examples include support contact volume, conversion rates, and churn.

Downstream metrics tell you what the work was worth. You don’t need to abandon the metrics you already collect, but you do need to build a bridge from them to the ones leadership tracks. The table below maps common upstream metrics to the business priorities they most directly connect to, with a suggested framing for each.

Famulegun also points out that the translation depends on access to data outside the UX team. I recall that my team had to fight with my company’s revenue operations team to get access to Salesforce data so we could make prioritization decisions with ARR as an input.

Famulegun:

The data you need already exists inside your organization. Partner with finance, product analytics, customer support, or marketing to understand what they track and to get access to before-and-after data for flows you’ve redesigned. Even directional data is persuasive when it’s honest: “Contacts about [feature] dropped 30% in the quarter following the navigation change.”

A practical note: this translation only works if you have access to downstream data. If your team isn’t currently connected to product analytics, customer support, or finance reporting, that’s the first conversation to have.

The goal isn’t to overstate what UX delivers. It’s to surface the connection that already exists between the work your team does and the numbers the business is tracking.

Diagram linking UX metrics to revenue, retention, and support outcomes.

Stop Reporting UX Activity and Report Business Outcomes

UX metrics matter most when teams connect them to the business outcomes leadership tracks, from revenue and retention to support costs and risk.

nngroup.com icon nngroup.com

Laura Summers, writing for the Pydantic blog, describes the strange math of coding agents: the work can run in parallel, but our attention can’t.

Marcelo, another Pydantic colleague, when asked about his Claude Code session freezing said: “just open 5 claude sessions. You’ll never notice because you’re busy giving feedback to the others.” He was joking. I think. But it captures something true about the current moment. The parallelism is exhilarating and kind of feral. The number of things you can start has dramatically increased. The number of things you can thoughtfully finish hasn’t changed at all, because that part still requires the one resource we can’t parallelise: your brain.

The design version is easy to recognize: an agent can generate dozens of screens and states while one brain still has to judge the product intent and every edge case. You may spend less time drawing the interface, but every state still demands a decision.

Summers calls the emotional cost “the human reward function problem”:

Here’s a term for what I think is happening: the human reward function problem. In machine learning, a reward function tells an agent what good looks like. Writing code by hand was never easy, but it was full of small rewards. Solving a problem in your head. Understanding a gnarly bit of logic. Watching the code compile. The feeling of control. LLM-assisted programming has automated much of the work that generated those dopamine hits and replaced it with the cognitive load of review and supervision. The satisfying part shrank. The exhausting part grew. And there are no new rewards to fill the gap.

If you’re feeling like your work is simultaneously more productive and less satisfying, you’re not broken. The feedback loop is broken. And I think we need to start treating that as an engineering problem in its own right, not a personal failure.

Person monitoring multiple coding-agent sessions on a computer screen.

The Human-in-the-Loop is Tired

Coding agents can multiply the amount of work started, but not the attention required to judge intent, review output, and finish work thoughtfully.

pydantic.dev icon pydantic.dev

I’ve intentionally covered loops a lot this week. It’s been the talk of the virtual town of late, so it’s an important concept to understand as AI-assisted software design and development continues to mature.

MC Dean pulls it all together practically for designers in this piece. She reminds us that designers need to stay in the conversation; be in the room where it happens:

The conversation about AI and design tends to run in one direction: here are tools you can use to do your job faster. That framing keeps designers in the task loop. Tools help you execute. The loop stack shows you where the real work is.

The real work is authoring the system loop. Writing the specifications that constrain how AI behaves. Encoding the quality standards that define what good output looks like. Making the judgment calls that no loop below the oversight layer can make on its own.

Taking a “loop stack” built by engineers, she adapts it for designers:

At the base: the execution loop. The model fires, tool calls happen, tokens generate. This is genuinely not your concern. You don’t need to understand transformer architecture to design well with AI, any more than you need to understand TCP/IP to design a good website.

One layer up: the task loop. The agent works on a specific thing until a condition is met, then stops. Who defines that condition? You do. “The task is complete when the output meets the brief” is a design decision. What counts as meeting the brief is yours to specify.

Then the product loop. This is the experience layer, the thing a person actually encounters. Does the flow hold together? Does the output feel like it belongs to a coherent system? Does it match the quality bar? Every heuristic you’ve ever learned, every design principle you’ve internalized, lives here.

Then the system loop. This is where the AI gets better, or doesn’t. The patterns it learns, the constraints it operates within, the values it embodies. Design systems, behavioral specifications, brand guidelines, content principles, tone of voice. Everything you’ve encoded about what good looks like. This is the layer that trains the loops below it.

At the top: the oversight loop. This is where human judgment lives permanently. Not as a checkpoint at the end. Not as a review gate before launch. As a continuous presence that can redirect anything in the stack at any time.

This is what we call “craft”.

In the full post, she shares a prompt for you to try that illustrates how the loop actually works. Go try it.

A glossy white sphere centered among flowing blue concentric waves and curved lines, suggesting gravitational pull or ripple effects.

/loop

Every AI conference this year was about loops. Here’s what that means for design, and a loop you can run in the next ten minutes.

marieclairedean.substack.com icon marieclairedean.substack.com

The interesting part of agent loops isn’t how to keep an agent running. It’s knowing when the work is understood well enough to let it run.

Peter Yang, interviewing Claude Code’s Thariq Shihipar on Behind the Craft, asks about Claude Code’s new loop, goal, and workflow features. Shihipar describes /goal less as an autonomy switch than as a signal that the uncertain work has already been done:

/goal is great when you have a complicated task and need to make sure it is done at the end. It’s the user indicating, “I’ve done enough specification and exploration. I understand the problem space. Just go execute on it, and if you run into something, fill it in.”

That puts a useful boundary around loop engineering: don’t ask the agent to power through ambiguity you haven’t investigated. Shihipar treats planning as the work of reducing that ambiguity:

We often talk about plans as one shot: you plan, then you do something, and that’s it. But planning is an iterative process of exploring, investigating, and finding out what you don’t know and what you want.

A few minutes later, he gives that process a better name:

I like to call it getting rid of your unknowns. With almost any task, there’s a lot you don’t know—either how things work or what you want. It’s very iterative. You don’t write it all down once and then implement it. There are many steps and different passes.

Implementation doesn’t end that process. Shihipar asks the agent to keep notes about what it discovers while building, then feeds those discoveries back into the specification:

The model can find things that it—or you—didn’t anticipate during implementation. I ask it to keep implementation notes as it goes: what did we not expect about this implementation? Once we have that, we can respec if needed. It’s much less one handoff from specification to implementation and more a back-and-forth process.

That’s the more useful loop: explore until “done” is concrete, build the smallest version that can expose what the plan missed, then revise the plan from what the build teaches you. Longer-running agents are the consequence, not the point.

Quotes lightly edited for clarity.

How I Plan, Build, and Run Loops with Claude Code in 40 Minutes | Thariq Shihipar

Thariq works on the Claude Code team, and I’ve wanted to see how he builds for a long time. In our episode, he showed how to use /goal to keep Claude working, how he plans with Claude to remove unknowns before building, and how he runs a team of agents in Slack. He also shared why his team cut…

youtube.com icon youtube.com

Jihoon Jeong asks the question: if the model starts fresh each cycle, what actually compounds? He uses software developer Geoffrey Huntley’s Ralph Wiggum loop to illustrate:

If the loop’s power came from looping — from persistence of effort, from the agent grinding away at the problem — then the longer you could keep one agent going, the better it should get. The opposite is true, and every practitioner knows it. A long agentic session curdles as its window fills with dead ends and stale state; the agent gets worse with continuity, not better. The winning configuration, rediscovered by everyone who runs loops at any scale, is maximum discontinuity: kill the agent every iteration, resurrect it blank, and let it inherit nothing except what the last iteration wrote to disk. Huntley’s design wasn’t naive. It was surgical. Discard the mind, keep the files.

Fresh context is only useful if the loop can tell progress from activity. Jeong puts that burden on the verifier:

Second, one of the five decisions is load-bearing in a way the others aren’t. The verifier is the wall the whole structure hangs on. A loop repeats whatever its verifier accepts; if the verifier is strong — tests, compilers, benchmarks, anything with teeth — the loop compounds progress, and if the verifier is weak, the loop compounds output. Every experienced loop practitioner converges on the same rule: the loop is exactly as good as its stopping test. A loop with a weak verifier isn’t an autonomous engineer. It’s an expensive random walk with excellent posture.

Jeong’s answer is that the model starts each cycle from scratch, while plans, tests, commits, and code preserve progress for the next one:

The loop works, and the skeptics are right about why its working is strange. It adds no intelligence. It makes no model smarter. It rents the same brilliance every cycle at full price, extracts what it can, and throws the brilliant thing away — keeping only the residue on disk, because the residue is the only part that compounds. It works better than it has any right to, exactly as I said last time. And its characteristic failure mode is now visible at scale too, and it is not a crash. It’s a flatline. The loop keeps turning, the tokens keep burning, and the density of correct answers stays wherever the verifier pinned it — because nothing inside the system learns from one cycle to the next. The agent that finishes iteration forty is precisely as capable as the one that started iteration one. Only the pile of files has grown.

Illustration for an article about verification and durable state in agent loops.

The Year of the Loop

Agent loops do not improve because a model remembers. They improve when durable plans, tests, commits, and verification preserve the right residue between fresh sessions.

medium.com icon medium.com

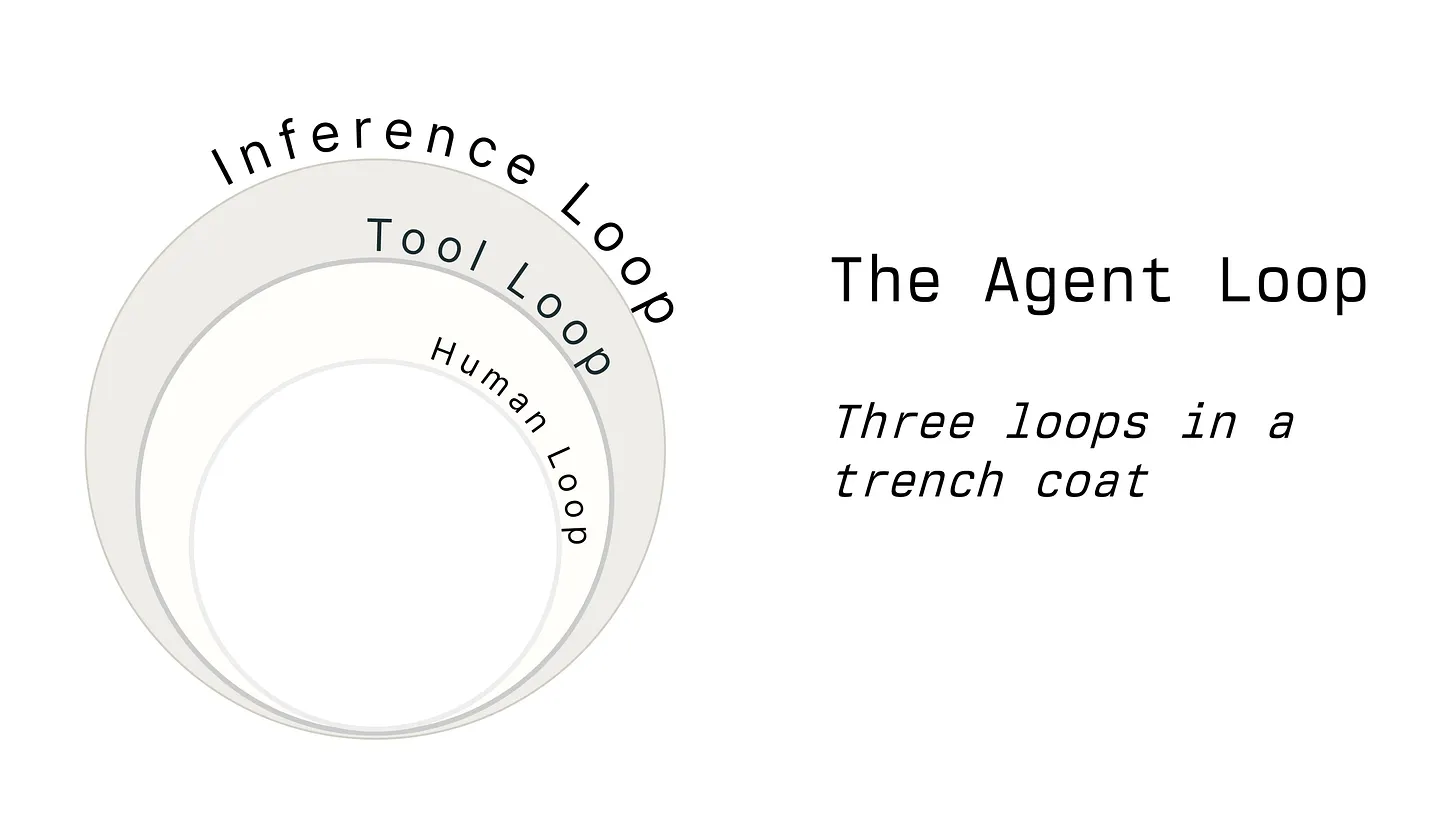
After Addy Osmani’s introduction to loop engineering, Robert Ross, writing at The Thought Drop, opens up the machinery. What looks like one agent loop is really three nested loops:

Agent loops are often oversimplified. They’re presented as a single loop, when really it’s three loops in a trench coat that make up an “agentic” experience for a customer. I’m here to write (yes, I wrote this, insane right?) yet-another-blog about agent loops. The example code blocks are also pseudo-code and for illustrating these ideas. Also I’ve omitted streaming, which complicates the post but the shape of these stays the same.

Those are the inference loop, which manages model calls and conversation history; the tool loop, which turns model output into actions; and the human loop, which approves, rejects, or redirects consequential work.

Ross’s “brain in a jar” analogy explains why the tool loop changes a model into an agent:

LLMs are brains in a jar. They provide no functional value on their own. The tools you give an LLM are what make it an agent.

When you tell a model “here are the tools you have” in your outer inference loop, the model may try to “use” them in its inference (response). This is the same thing as a brain sending an electrical signal telling your index finger to hover over the enter key of the email you desperately want to send Laney. Tom, we need to set boundaries my man.

The separate tool definitions you include in your API request are usually serialized into the system prompt field of the token stream the model processes. And it may infer the usage of multiple tools in one turn. (Hence: Tool Loop).

The human loop is the final layer—and the hardest to build:

The Human Loop is arguably the hardest part to implement in agentic systems. You can’t have a piece of code block for hours. What if the server restarts? What if you have thousands of other requests coming in you need to respond to? The first two loops (inference and tool) are simple enough. The human loop ups the ante of difficulty. This is why durable execution frameworks exist, like Temporal.

But the human loop is necessary, because it’s the only thing stopping Tom from actually sending that message to Laney. IT WAS TWO YEARS AGO TOM, MOVE ON!

Three nested circles labeled inference loop, tool loop, and human loop beside the article title.

The Agentic Loop: Three loops in a trench coat

Agentic systems are not one loop but three: inference, tool use, and human oversight. The last is the hardest—and the one that keeps consequential work accountable.

bobbytables.io icon bobbytables.io

We’ve heard about prompt engineering and then context engineering, and now it’s loop engineering. Googler Addy Osmani offers a clear introduction to it, beginning with a simple definition:

Loop engineering is replacing yourself as the person who prompts the agent. You design the system that does it instead. A loop here can be thought of a recursive goal where you define a purpose and the AI iterates until complete.

What changes is who keeps the work moving:

For like two years the way you got something out of a coding agent was you wrote a good prompt and shared enough context. You type a thing, you read what came back, you type the next thing. The agent is a tool and you are holding it the entire time, one turn after the other. That part is kind of over, or at least some think it’s going to be.

Now you build a small system that finds the work, hands it out, checks it, writes down what is done and then decides the next thing, and you let that system poke the agents instead of you. I wrote before about the cousin of this, agent harness engineering, which is making the environment one single agent runs inside and the factory model - the system that builds the software. Loop engineering sits one floor above the harness. The harness but it runs on a timer, it spawns little helpers, and it feeds itself.

And the loop itself has a recognizable anatomy:

A loop needs five things and then one place to remember stuff. Let me list it first and then map it.

  1. Automations that go off on a schedule and do discovery and triage by themselves.
  2. Worktrees so two agents working in paralell dont step on each other.
  3. Skills to write down the project knowledge the agent would otherwise just guess.
  4. Plugins and connectors to plug the agent into the tools you already use.
  5. Sub-agents so one of them has the idea and a different one checks it.

Then the sixth thing, the memory. A markdown file, or a Linear board, anything that lives outside the single conversation and holds what’s done and what is next. Sounds too dumb to matter. But it’s the same trick every long running agent depends on and I went into it in long-running agents, the model forgets everything between runs so the memory has to be on disk and not in the context. The agent forgets, the repo doesnt.

Illustration accompanying Addy Osmani's article on building recursive coding-agent loops.

Loop Engineering

Loop engineering moves the work from one-off prompts to durable systems that discover, delegate, verify, and remember work while humans remain accountable for the result.

addyosmani.com icon addyosmani.com

Slack Design Ops practitioner Sheila Kazan begins with a question designers were asking privately:

“How do I use AI?”

That question, typed in a DM rather than asked out loud, told us everything. Our design team was not short on curiosity. What was missing was somewhere to be a beginner. A space where not knowing wasn’t a liability, but the whole point. So we built one. In true Slack fashion, our AI origin story starts with a Slack channel and a lot of enthusiasm.

Kazan on why Slack built its own program:

The problem wasn’t a shortage of learning opportunities. It was the opposite. Tool enablement sessions started flooding our calendars from every direction, and almost none of them were built with designers in mind. Most of these sessions were designed for engineers, and we were just along for the ride. There was another wrinkle: things were moving so fast that a setup guide from Monday was outdated by Friday.

So we decided to build our own AI enablement programming. For design, by design.

That phrase became our north star. Hearing what AI tools can do from a fellow designer lands completely differently than hearing it from an engineer. It wasn’t evangelism. It was permission, and for the designers on our team who were still waiting to be convinced, that distinction mattered more than we expected.

Kazan on an outcome that doesn’t show up in a prototype:

And you know what? That’s okay. That’s also a really good finding. Not every designer walked away with a working prototype or a merged PR. Some walked away with something harder to measure and more important: a clearer sense of where they currently stand with this technology, what excites them, what makes them uneasy, and what questions they still need to answer for themselves.

That’s the thing about building a learning culture: the value isn’t always in the output. Sometimes it’s in the container. When people know there’s a place to bring their confusion, they bring it. And when confusion is visible, it becomes something the whole team can work on together.

Design leaders should budget for the learning environment alongside the licenses.

Cover for Slack Design's Builder Days, where designers learned to build with AI together.

We Didn’t Teach Our Designers AI: We Built a Place Where They Could Learn It Together

Slack Design didn’t run another tool-enablement session. They built a place to be a beginner—for design, by design—where not knowing was the whole point.

slack.design icon slack.design

Phil Morton, who writes about product design, research, and AI, argues that design teams can’t adopt AI one designer at a time. The process only changes when design and engineering change it together:

New ways of working mean that designers and engineers have to work closely together. The ideal is that you’re in the same code repository as the engineers, not throwing a Figma file over the wall.

For most teams that’s a long way from today. Designers and developers might sit in the same squad, but they’re still siloed, with a big handover in the middle.

So when you’re trying to work out what your AI design process is going to look like, you’re not just choosing new tools for yourself. Your engineering partners have to adopt the same approach, because it makes no sense for you to work one way and them another.

The handoff is the stubborn part. A designer can learn Claude Code and still end up handing a different artifact across the same organizational boundary. Without a shared repository, components, and review process, the team has improved one person’s output while leaving the production system alone. Tool fluency helps, but it doesn’t create a shared way of working.

Morton also shows why there can’t be one standard AI workflow for every design project:

In the old way of working, the output was roughly the same whatever the project: a high-fidelity Figma file.

Now it varies wildly. If you’re assembling a feature on an established product with a mature design system, you barely need Figma at all. AI is good at using existing components and you’re not asking it to do any visual design, which it’s bad at. You can sketch the rough idea, have it assemble it and iterate. There’s little point building a pixel-perfect version by hand first.

But if you’re working on a new product which needs its own visual design or brand, it’s a different job. AI can get to a rough wireframe using generic components, then it stalls. Creative and original visual design still needs a human.

Illustration for an essay on why design teams struggle to adopt AI without changing how they work together.

Five reasons design teams are struggling to adopt AI

Design teams can’t adopt AI one designer at a time. The process only changes when design and engineering change it together, sharing a repository instead of a handoff.

philmorton.co icon philmorton.co

Vaughn Tan, an organizational researcher and author of The Uncertainty Mindset, argues that organizations routinely mistake uncertainty for risk. Targets, forecasts, and cost-benefit analysis assume the choices and their odds are already knowable. New ideas rarely arrive with that evidence attached.

It probably didn’t die because it was bad. Your organisation wanted something new, so it did what its machinery does: it made the new thing a big bet. Under uncertainty, big is the wrong move in two ways. A big bet on the new is not bold; it is necessarily blind, because you cannot know enough up front to justify it. And a big, visible bet is just what the parts of an organisation that want to keep things the same will move to get rid of. The better the idea, the bigger the bet you are tempted to make, and the bigger the target you paint on it.

The trouble with a flagship is that its visibility becomes part of its risk. Tan’s alternative is to make experimentation less dramatic and more routine:

The moves to make are the undramatic ones. Start small enough that no one sees a threat. Make tests cheap, fast, and numerous, so failure is survivable: a portfolio of small bets each placed to answer useful questions, instead of one big bet placed to create the impression of decisiveness. Disguise the innovation as an unremarkable update to standard procedure. The idea is to not fight the system head-on.

This is a useful distinction for design leaders. A large commitment tries to prove confidence before the team has learned enough to deserve it. A portfolio of reversible tests turns the same resources into evidence.

If this sounds like working behind the organisation’s back, consider what the alternative gambles with. The innovation big bet stakes public money and public trust on a guess, faking certainty about something genuinely uncertain. The small, quiet experiment spends almost nothing to buy real knowledge, and the public is never exposed to a large, irreversible downside. Being responsibly sneaky isn’t cheating. It’s how you take care of public resources in a world you cannot predict.

The responsible move under uncertainty is to keep failure cheap and learning continuous. In other words, get prototypes in front of customers as soon as you can.

Screenshot of the article page at vaughntan.org.

Against bigness

Organizations say they want innovation but keep killing it, because their decision-making machinery treats uncertainty as if it were risk. The fix is small, quiet, reversible experiments instead of big visible bets.

vaughntan.org icon vaughntan.org

Dan Maccarone, founder of the product-design studio Charming Robot, recounts what changed after a year rebuilding its process around AI:

Before anyone accuses me of sneaking speed back in through the side door: the sprint is still five days, and nobody here got faster at design. What went away was the relay.

This time, we built all five states at once. Live. Interactive. Flip a toggle and watch the page rearrange itself for a logged-out stranger versus a power subscriber. Switch to mobile and it’s already there. Same five days, an order of magnitude more product. The work got deeper, and depth was the thing that, for years, blew out schedules and drove us crazy with minute details in UX and design.

This is what redesigning the factory floor looks like: not making each station faster, but removing the relay and reorganizing the work around what AI makes possible. The practical advantage is broader attention. More of the product becomes available for judgment before it hardens into implementation.

And because that documentation is generated from the prototype instead of maintained next to it, it cannot become out of date. Every change order rebuilds it. Move a state, kill a screen, rethink a flow, and the user stories, the acceptance criteria, and the error conditions regenerate to match what is actually there. You can lay the docs and the working prototype side by side and catch a contradiction in seconds, while it is still cheap to fix.

But a prototype can preserve the current answer without preserving the reason for it. Maccarone’s experience brief keeps that responsibility on the human side of the workflow.

The one that’s really going to hurt you is much more subtle and is rarely communicated. It’s the why. Why this flow and not that one. Why this default, this state, this tradeoff. The AI never writes that part down, because the AI never had a reason in the first place.

Because AI is so good at producing a confident, finished-looking deliverable, the temptation is to let the prototype become the spec, to let the thing that looks done stand in for the thinking that was supposed to happen first.

Illustration for an essay on rebuilding a design studio's process around AI thinking, not prompts.

Never mind the prompts, here’s the thinking

A studio rebuilt its entire design process around AI over a year. It didn’t get faster, and that’s exactly why it worked: the relay went away and the work got deeper.

uxdesign.cc icon uxdesign.cc

Patrick Neeman is making an argument I’ve returned to repeatedly: as AI makes production cheap, designers’ value shifts toward judgment—knowing what good looks like, choosing the right problems, and owning the outcomes. I’ve called this the orchestrator gap: agents execute; judgment stays human. Neeman extends that argument by locating craft itself in that judgment, without pretending execution no longer matters.

The production layer — the wireframe, the boilerplate, the competent first draft of a screen — is collapsing toward free, which changes our own perceived value proposition.

When making gets cheap, much of what you called craft turns out to be production wearing craft’s clothes. What survives is the part that was never about the file: choosing the right problem and owning the outcome it moves. Not a loss but a relocation you can get ahead of. Here is where craft goes.

Craft is not decoration on the product. It is part of what makes the product worth trusting.

When a tool can generate a thousand plausible screens before lunch, the scarce skill is no longer making one; it is knowing which one deserves to exist. That skill has a name, taste, and most people have been outsourcing it to whoever runs the critique.

None of this means polish stops mattering. It means polish is table stakes, not the differentiator. The differentiator is the judgment that points all that cheap production at a problem worth solving in the first place.

That judgment is also what earns trust. Users never see your process, but they feel its absence. A product built on the right calls feels coherent and reliable, and reliability is what brings people back; one built on plausible guesses feels off in ways people cannot name and do not forgive.

Neeman on teaching that judgment to a machine:

Most craft is tacit. You know a layout is wrong before you can explain why. You feel that a flow has one screen too many. Michael Polanyi named this decades ago: we know more than we can tell.

Your taste lives mostly below the waterline of language, in pattern recognition you built over years and never had to state, because your own hands did the work. That gap is harmless when you do the work yourself. It becomes the whole problem the moment you hand the work to a machine.

Point a model at a vague brief and it fills the silence with its own defaults, which is the average of everything it has seen. Average is exactly what craft is supposed to beat.

I agree with Neeman: writing the standard requires the same judgment the standard is meant to preserve.

Illustration for an essay on how design craft shifts from production to judgment as AI matures.

Craft still matters, but it’s about outcomes

As AI makes production cheap, craft relocates from making the file to choosing the right problem and owning the outcome. Not a loss, but a relocation you can get ahead of.

uxdesign.cc icon uxdesign.cc

Wouter de Bres built a free online book about psychology for designers. Forty chapters, organized around four areas: the people you design for, the interface you put in front of them, your own cognition while designing, and the organization that can override all of it before you ship. The introduction explains why he made the site:

Every decision you make as a designer is a claim about how a person will think, feel, or behave. Where you put a button is a claim about where people look. What you show on an empty state is a claim about what people need when they feel lost. Whether you use a progress bar is a claim about how people experience effort. You make these claims every day. The only question is whether you make them with understanding of how people actually think and work, or just with a gut feeling and a deadline.

That is the useful provocation: design is already full of behavioral claims, even when nobody names them that way. Chapter 14 goes after “intuitive”:

“Intuitive” is one of the slipperiest words in a design review. Designers say it all the time and nobody pushes back because it sounds like evidence. Usually it is not. Most of the time it is just a description of how familiar the designer feels with the thing they made, and that is a weak way to judge whether it will work for someone else.

Most of the time, intuitive just means familiar.

That chapter is the internal trap: designers can mistake their fluency for the user’s. Chapter 27 is the external version of the same problem, where teams underestimate how expensive it is for users to leave an existing routine:

This is what teams underestimate when they say users are irrational for sticking with a worse tool. They are not running a fresh comparison every morning. They are moving inside a routine that already became cheap to repeat. Less thought. Less searching. Less risk. Your product may be better once it is learned. The old one is better at 9:03 a.m. on a busy Tuesday.

A lot of product strategy gets built around the wrong moment. Teams compare tools in a calm demo state. Users switch in the middle of real work, with deadlines, interruptions, and habits already in motion.

The two chapters work well together because they correct the same designer bias from opposite sides. Inside the team, “intuitive” often means “familiar to us.” Outside the team, a worse incumbent can still win because it is familiar to the user. The design implication is brutal but useful: better is not enough. The experience has to be easier to understand, easier to try, and cheaper to switch into during real work.

Cover image for Wouter de Bres's free online book 'Product Design Psychology'.

Product Design Psychology

Understand the minds you design for and the mind you design with.

productdesignpsychology.com icon productdesignpsychology.com

Drew Breunig, an analyst and developer who writes about AI infrastructure, has a name for the slow accumulation of fixes, workarounds, and escalating all-caps instructions that eventually choke an AI application: prompt debt.

The plain-English prompt that makes prototypes effortless turns out to be a poor way to specify how a system should behave, and the bill arrives slowly, disguised as ordinary progress, until the application can barely move. The problem is not any single prompt. It is that natural language was never meant to be a specification language for engineering, and treating it as one quietly caps what you can build.

Breunig’s model-lock-in evidence is the warning sign. A recent Datadog report shows GPT-4o is still the most-used model in observed traffic; Breunig also says multiple large inference providers put GPT-4o and similar-vintage models above 50% of all calls. His proposed escape hatch is to stop treating hand-written prompts as the durable layer:

Every mature engineering discipline eventually stops doing by hand the very thing it once prided itself on doing by hand. Assembly gave way to compilers, hand-tuned queries gave way to planners, and manual memory management gave way (mostly) to machines that do it better. Prompt-writing is no different.

Coaxing the model with exactly the right words is a real skill, and for one-off tasks it’s often optimal. But to build reliable, improvable, and portable systems we should not be hand-tuning prompts.

For designers, the useful warning is not that prompt craft goes away. It is that fragile prompt craft stops scaling once the AI behavior becomes part of the product. If the system has to survive a model upgrade, the design work has to move into measurements and typed specifications: schemas or contracts that constrain what the model can produce and give the next model something stable to inherit.

Preview image for Drew Breunig's essay 'The Problem is Prompt Debt'.

The Problem is Prompt Debt

The plain-English prompt that makes prototypes effortless turns out to be a poor way to specify how a system should behave, and the bill arrives slowly, disguised as ordinary progress, until the application can barely move.

dbreunig.com icon dbreunig.com

Heenesh Patel links Apple’s WWDC 2026 moves (Siri now able to invoke app functions without the user ever opening an app) to a larger skill shift for designers. The polished-UI moment isn’t ending, he argues; its shelf life is just shorter than we think.

This moment might be shorter lived than expected, as we enable agents to execute more tasks on our behalf, screen-based flows fold in on themselves to intents, replaced by API calls and lightweight confirmations. Here the beautifully crafted experience still matters, but it’s not where the experience lives.

As designers continue to rapidly evolve their skills in an AI first world, taste judgement can elevate the experience but only so far and the real differentiator in app design becomes the overall experience architecture, and how flexible and robust apps are in embedding into the platform.

Patel locates the new value in how flexibly and robustly an app’s functions embed into the platform. That is a systems problem before it is a screen-design problem.

Taste is the skill of this moment. Systems thinking is the skill that will become indispensable in the next chapter of design. Designers who start building that capability now will be the ones setting the standard when the shift arrives in full.

The uncomfortable implication in Patel’s urgency: Job Stories (a way to frame user intent in context) and state charts (maps of the states an experience can reach) have been in the UX toolkit for years. What changes is the operating system. If Siri can trigger app functions directly, and if users can move through an experience by intent instead of by screen, designers need to understand the states, permissions, handoffs, and failure paths that sit behind the interface.

Preview image for a UX Collective article on systems thinking as a core UX skill.

Why systems thinking is becoming the most important UX skill

As apps become more context-aware, the designer’s job is shifting from shaping screens to shaping systems.

uxdesign.cc icon uxdesign.cc

Nolen Royalty, a software maker who writes at eieio.games, gets at a problem with AI-generated work that shows up before judgment: the effort signal. His examples include tldraw, the collaborative drawing tool, closing AI-generated pull requests, warm-cream Claude websites, and record collecting, but the point is simple. Polish used to be a proxy for care. Now it isn’t.

What software (and writing, to an extent) is missing now is legibility of effort - the ability to tell at a glance whether something took a human meaningful work.

Until recently, “someone cared enough to write this” was an ok heuristic. Plenty of writing on the internet was bad, but you could convince me that you cared about something just by writing it down.

Of course, generating plausible-looking text - or a plausible-looking website - is trivial now.

For designers, that broken proxy is already visible on the surface. We can all spot the default Claude style now, which is funny until you realize that a visual pattern has become an accusation about how much thought went into the site.

There’s nothing objectively wrong with making a website with a warm-cream background and hero text in a sans-serif font with a single accent word that uses an eye-catching color and a different font.

But when I see a website that has the default Claude style I assume that the author put ~no thought into how the site should look. And I often assume that the author didn’t put too much thought into the rest of the site either.

That’s not fair of me! But “someone made this website” is no longer enough to tell me that the website was important to them. So “default Claude style” is one of my new heuristics.

Taste sounds less mystical when you put it this way. A designer doesn’t make a screen human by avoiding beige or picking a stranger typeface. The work is in the decisions: why this hierarchy, why this contrast, why this interaction, why this amount of friction.

The proliferation of digital music and streaming made having a music collection easy and frictionless. And so a subculture evolved to re-add that friction.

And in small ways I think you see the same things happening now.

I’ve seen people joke about adding typos to emails to prove that they wrote them. MS Paint-style image macros read as more human than detailed, funny images (the image could be AI slop). Websites that look intentionally bad are more interesting than websites that look beautifully bland.

Blog hero graphic for an essay on the legibility of effort in an age of AI-generated work.

Legibility of Effort

LLMs have broken legibility of effort - our ability to tell, at a glance, whether something took a human real work. What happens next?

eieio.games icon eieio.games

The easy story about AI in creative work is that it closes distance: idea, prompt, output, iteration, all compressed. It’s Nice That gets at the more designerly version of that question by putting creative technology’s appetite for “happy accidents” next to design’s need for control:

“From the technology approach, the metaphor I equate it to is the classic ‘happy accidents’ you have when you are in a design tool,” Seth says, finding expected moments of creativity. “The best happy accidents aren’t just between a person and a tool; they happen between people.” It’s perhaps in this notion that co-creation is at its most visible, not in the technology itself, but rather in the conversations and unexpected developments that occur when people with different perspectives work closely together. For Talia, however, this isn’t the case. “Nothing we do is experimental by nature,” Talia says, “everything is incredibly controlled – or, better yet, ‘designed’,” stressing the importance of the role of the designer and the meaning behind design itself. “Design is about creating solutions; there is a sense of control, there is a purpose, there is a function,” she continues, “even the beauty is controlled to a degree.” An example is the generative motion graphics system that Talia created, in collaboration with Mother, for the Crypto coin USDC.

Designer and coder Talia Cotton’s line clarifies the whole piece: “controlled – or, better yet, ‘designed’.” Cotton’s point is that the speed of generation only makes the designer’s eye more important, because someone still has to decide the boundaries before the machine starts producing variations.

Cotton’s USDC system makes that concrete:

Within the visual identity, Talia developed a custom tool that generated guilloché patterns, in reference to the historical patterns used in traditional finance. Alongside set, systematic parameters – including height, width, density, and speed – Talia had to create algorithmically constrained rules within those limitations. “As you adjusted one parameter, another parameter would automatically change its available range,” Talia says, “that ensured every possible output looked good.” As Talia suggests, especially considering the ease with which people can generate things, the “designer’s eye” is now more important than ever. “The designer’s job is to create an airtight generative system that considers every possible case and every possible output,” she says, “so that every single output always looks great, no matter how different it is.”

Editorial feature image for It's Nice That on closing the gap between thinking and making.

What happens when the gap between thinking and making closes?

Seth Akkerman and Talia Cotton explore how co-creation dissolves disciplines and why design stays a controlled, intentional act.

itsnicethat.com icon itsnicethat.com

Karo Zieminski, in her newsletter Product with Attitude, is writing for builders, founders, and PMs, but the design translation is straightforward: AI fluency without critique is just a faster way to lose your ability to evaluate the output for yourself.

She draws the distinction:

Plain AI literacy means knowing how to use AI tools. It means learning to prompt, create automations, and bring AI into your workflows.

Critical AI literacy goes further. It adds systems awareness: understanding that AI is not just a tool on your screen, but part of a larger system of model choices, product decisions, business incentives, policy constraints, ethical tradeoffs, and human consequences.

Attitude is the posture that turns AI literacy into critical AI literacy.

That word, posture, matters. It is the same split in not outsourcing the learning: the tool doesn’t determine whether you get sharper or softer; the way you use it does.

Zieminski puts research behind that concern:

The data is on the table now. Microsoft Research surveyed 319 knowledge workers in 2025 and found that higher confidence in the AI is associated with less critical thinking, while higher confidence in yourself is associated with more. MIT Media Lab’s “Your Brain on ChatGPT” study measured the same erosion at the level of brain activity. The muscle is real, and it atrophies on schedule.

For designers, the warning is: don’t let the tool do so much of the looking, choosing, and checking that you stop building those muscles yourself.

Zieminski defines the working posture plainly:

AI with attitude means using AI with judgment, boundaries, curiosity, and scrutiny. You enjoy powerful tools without worshipping them, panicking about them, or letting them decide how you think, work, create, and learn.

Newsletter hero image for an essay on critical AI literacy and using AI with attitude.

Use AI with Attitude, or Become the Product.

Use AI hard. Just don’t kneel for it. A field guide to critical AI literacy and attitude.

karozieminski.substack.com icon karozieminski.substack.com

Sen Lin, writing in UX Collective, has a useful reference for designers who want Claude Code to fit their workflow instead of acting like a generic engineering agent:

Claude Code is an agent, and an agent is only as good as how you configure it. That’s the part worth paying attention to as a designer: Out of the box it leans engineering, but you can set it up to fit how you actually work — to understand design, respect your workflow, and carry the right capabilities — so it produces better results, faster.

A technical stack is the set of technologies you decide on before writing a line of application code. A design stack is the same idea, applied to Claude Code: the brief, the design knowledge, and the tools you hand the agent upfront.

The useful move is treating Claude Code setup as a design operation, not a prompt-writing trick. Give it a project brief, a design-system guide, and the right tools before it starts touching the work.

If CLAUDE.md is the brief, DESIGN.md is your design system translated into something an agent can read and obey. It’s a format specification that describes your visual identity to a coding agent: the exact values, and the reasoning behind them.

The file works on two layers, and both matter.

The first is machine-readable design tokens, written as YAML front matter — the exact values, so the agent never has to guess what gray-500 resolves to or which surface color a modal should use: […] The second is human-readable design rationale, written as prose — the part that explains why a value exists and how to apply it. Tokens tell the agent what primary is. The prose tells it there should never be more than one primary button per view, that a primary action is always paired with a neutral or subtle one for cancel, that button width is set by the parent and never hardcoded.

The tool/instruction split is the part worth saving:

MCP gives the agent access to tools.

Skills give it the knowledge to use those tools well.

Where MCP is access, a Skill is a markdown-based guide that teaches Claude how to perform a specific task in a specific way. It’s a set of instructions, scripts, and resources — a training manual that keeps the agent from wandering down expensive detours and burning tokens on the wrong approach.

Good checklist. The designer’s job is not just to ask Claude Code for UI. It is to onboard the agent into the product, the design system, and the working style before generation begins.

Article hero image for a guide on configuring Claude Code with a designer's design stack.

Why your Claude Code needs a design stack

The setup that makes Claude Code fit into your designer workflow.

uxdesign.cc icon uxdesign.cc

Designer and writer Christopher Butler is writing about AI, but this also lands on the mechanics of agent loops. A loop can keep running, but useful output still depends on the constraints, preferences, success criteria, and taste made explicit before it starts.

Butler, on what stays human:

The more interesting situation is the one where we keep the thinking and hand off only the doing — and what happens when we do.

What happens is more than speed. When you have to describe what you want to the agent — with enough precision that what comes back is what you actually wanted — you begin to think about the thing differently. Description, it turns out, is where the idea often actually gets made. You start by knowing roughly what you want, and the act of articulating it produces a clearer want, which produces a sharper specification, which produces a better thing. Then you do it again. The thing improves; so does the thought.

That maps to the AI bottleneck I keep seeing: production speeds up, but judgment still happens at human speed. Butler isn’t arguing for slower tools. He’s arguing that useful AI makes the thinking more explicit, not less.

The friction is part of the point:

The agent’s current maturity requires a level of input precision that a competent colleague does not. At first, this can be a frustrating blocker; we’ve depended upon a different kind of intelligence in our peers — the kind that requires no elicitation. The machine does. But in a sense, this is a gift. It forces you to think the thing through in places you might otherwise have left fuzzy.

That’s the designerly translation. The machine doesn’t infer your hierarchy, tone, edge cases, or tolerance for risk unless you put them somewhere it can use. That friction is useful because the agent forces you to specify the fuzzy parts before it starts generating the same mistake everywhere.

Butler’s word for that retained work is investment:

This system depends upon me to provide the thinking. The agent does the doing. The structure is, I think, the practical form of the argument: the systems carry the doing, and they carry it well precisely because I have spent the time to think them carefully through. We like to call this intellectual property, which I think is a bit obnoxious. It’s really intellectual investment. Every technological advance should be measured not by the measure of intellectual property it absorbs — how much it can do without us — but by how much intellectual investment is worth sowing in it.

That’s the useful correction to “AI will do the work for us.” It will, but only the part of the work that can be expressed well enough to delegate. For a design system, that means brand rules, component logic, editorial standards, and good taste have to become rules, prompts, specs, tokens, and checklists the agent can actually use.

That leaves the tool in its proper place. Using AI lazily will produce plenty of forgettable output. The more interesting use treats it as a medium that rewards the thinking you put into it.

Of course, there is tension between expressing our specs as words and spatial manipulation as visual thinkers.

Screenshot of the article page at chrbutler.com.

Keep the Thinking

Christopher Butler on keeping the thinking and handing off only the doing—and why describing what you want with precision is often where the idea actually gets made.

chrbutler.com icon chrbutler.com

Claire Vo on her How I AI podcast gives a plain-language walkthrough of agent loops in Claude Code and Codex. The episode is technical, but the useful translation for designers is familiar: define the job, give it tools, decide what good output looks like, and make the system prove it. Once an agent can run without you, the interface problem moves into instructions, permissions, and checkpoints.

And then a couple other foundational things that I think are helpful when you’re running loops. And why are these things helpful before we get into what they are? They just keep the work clean.

If you are going to be yolo-ing loops all over the place, you’re going to want some consistency in execution, you’re going to want clean workspaces, you’re going to want conflicts resolved and avoided. And so, all these things are really to make those loops effective.

And so, what are the things? They are work trees. I feel like this entire podcast could be Git 101. But work trees are just basically a way to isolate the work, especially the coding work of an agent away from other agents’ work in a sandbox. There are skills, repeated ways to do common tasks. We have a full episode on what skills are from earlier last year when they came out. Plugins and connectors, these are just the tools that your agent has access to. […] Sub agents, both Codex and Claude Code allow you to kick off sub agents. This is just a way to federate out work from the main thread, so that sub agents can do specific tasks, especially validation. And then there’s some way to track state. And essentially just think of this is like a to-do list.

The practical translation for agent orchestration: write the operating conditions around the work before asking for the artifact.

Calling it a loop makes it sound like automation plumbing. The design work is the brief: what the agent can touch, what tools it can use, and how it knows it is finished.

The employee comparison makes the loop feel less exotic:

Now, people are going to ask, “What should I use a loop for?” And when you’re designing loops or designing agents, I say this is the time for the manager. You are designing a job. And so, just imagine that you’re onboarding an employee. That employee could be an executive assistant. That employee could be a customer service agent. That employee could be a software engineer.

Every Friday, EA, I would like you to review my calendar, see who canceled on me, where I could have used my time more effectively, if there are any follow-ups, and send me a Slack to get this done. Um and I want you to do that every Friday. Guess what? You’ve just designed a loop for your executive assistant. […]

So, I really like to think about loops as designing workflows and designing jobs to be done for people. It just happens to be that you can put this intelligent agent against the loop, and then it’s ready to go.

For designers, that last sentence is the translation layer. A designer already knows this move from creative direction: clear constraints produce better work than a blank request. The only difference is that the worker now happens to be software.

A loop without success criteria is just a faster way to make someone review the same ambiguity at a higher token cost.

We all want our agents to work for us on a schedule whenever we want, doing work that we don’t want to do. It’s great. What are some of the problems? One, loops can get expensive. So, I just kicked off an automation that happens on a regular basis. It does wide-ranging work. It decides when to spin off sub agents.

And it does loop-based validation, which means it’s burning tokens until it hits a threshold that it decides is successful. If you do not write that loop well, or your validation criteria is too thin, guess what? Your agent is going to burn tokens. I think we’ve seen this with open claw in particular or some of these agent harnesses is they’re really good at loops. They’re very diligent. They get interesting work done, but man, do they love to burn tokens.

[…] Loop-based prompting is just its own thing. Goal-based prompting in specific is just its own thing because you have to be very precise about evaluation and success criteria. If you are not, you will be very disappointed and use a lot of tokens for not a lot of output.
How to write AI agent loops in Claude Code and Codex

Claire Vo breaks down every agent loop type—heartbeat, cron, hook, and goal—from scratch: when each fits, and the worktrees, skills, subagents, and validation criteria a loop needs before it touches production.

youtube.com icon youtube.com

Jenny Xie, writing for Figma, talks with Vice President of the Pantone Color Institute Laurie Pressman about color as a cultural language, not a decorative layer. Pressman’s starting point is that color is read, not just seen:

Color is tied to our emotions and how we interpret the world. It’s a language that reflects what’s taking place in culture.

The practical questions Pressman gives designers are “What message am I trying to convey?” and “how do I use color to help me get there?” That’s the design-system version of brand strategy: what does this choice need to make legible before anyone reads the copy?

Xie follows that with examples where the same hue changes meaning across cultures, media, and materials:

Like any language, the language of color comes with its regional dialects. While black is worn at funerals in the West, mourners in the East wear white. Depending on the context, red can convey love, anger, or urgency in the West; in the East, it’s associated with luck, prosperity, and celebration. Brand and marketing teams can’t just follow color trends or assume universal meanings. “Someone seeing a product on the shelf in Japan versus France is going to have a different color sensibility,” says Laurie, “because they’ve built up certain associations.”

Pressman also brings this back to process:

Colors don’t exist in a vacuum. They show up differently depending on the material, medium, or surface. Something that resonates on a screen may look garish in person; a hue that exists in fabric dyes may not be achievable on, say, a Band-Aid. “This is why you must consider color at the inception of the design process,” Laurie advises, “so you can make decisions with full context of the material and surface finish on what it will appear.”

Illustration of a person in floral light-blue trousers walking a black path through orange flowers on a bright yellow ground.

Speaking the Language of Color

The Pantone Color Institute explains how brands can use color to shape meaning and drive trends.

figma.com icon figma.com

There are two versions of the same design-systems worry. One is about craft: AI can make an interface look considered without teaching anyone how the system works. Design-systems expert TJ Pitre pushes on the governance version: once the system is machine-legible and agent-friendly, who owns the calls the machines are allowed to make?

So when I say I have a beef with “agentic design systems,” understand that it isn’t a beef with agents. It’s a beef with one specific move that the term smuggles in, and that most people repeating it haven’t noticed they’re endorsing.

Here’s the move: handing the judgment layer of a design system to an autonomous agent loop that no human owns.

That’s the whole problem. Everything else is just tooling, and the tooling is great.

Design systems as AI infrastructure only works when the infrastructure still has an owner. Make the system machine-readable. Let agents generate, document, test, and check against it. But Pitre is correct that the library is only useful if the standards still have an accountable owner.

Strip away the Figma libraries and the Storybook instances and ask what a design system actually is. It’s a set of decisions an organization has agreed to and committed to enforcing over time. What does “primary action” mean here. When do we break our own grid. Does this thing deserve to exist as a component at all, or are we about to enshrine a one-off into the canon forever.

Those aren’t generation problems. They’re judgment calls, and they carry consequences the organization is accountable for, to its users, its engineers, its brand. A design system is, underneath all the tooling, a way of encoding collective judgment and holding people to it.

Pitre turns that into a test:

Which gives you a clean test for any “agentic design system” claim you encounter. Ask: what rejects the agent’s output, and who decided the rule it’s being rejected against? If the answer is a human-owned gate, it’s the real thing. If the answer is “another agent checks it” all the way down, you’ve built vibe coding with extra infrastructure and a more confident logo.

And that version is arguably worse than a person vibe coding in a scratch repo, because it launders drift through the authority of the system. The output looks sanctioned. It came from “the design system.” Nobody chose it.

In the end the invisible hand of the designer must still be felt.

Article hero for a critique of agentic design systems and who owns the judgment an agent is allowed to make.

My Beef with Agentic Design Systems

I build with agents every day. That’s exactly why this term worries me.

southleft.substack.com icon southleft.substack.com